2025 · Graduation thesis, 94/100 · Web (desktop browser)
Talk to a 3D AI host, right in the browser.
A real-time voice assistant with a face, built as my graduation thesis. No install, no GPU, no headset.
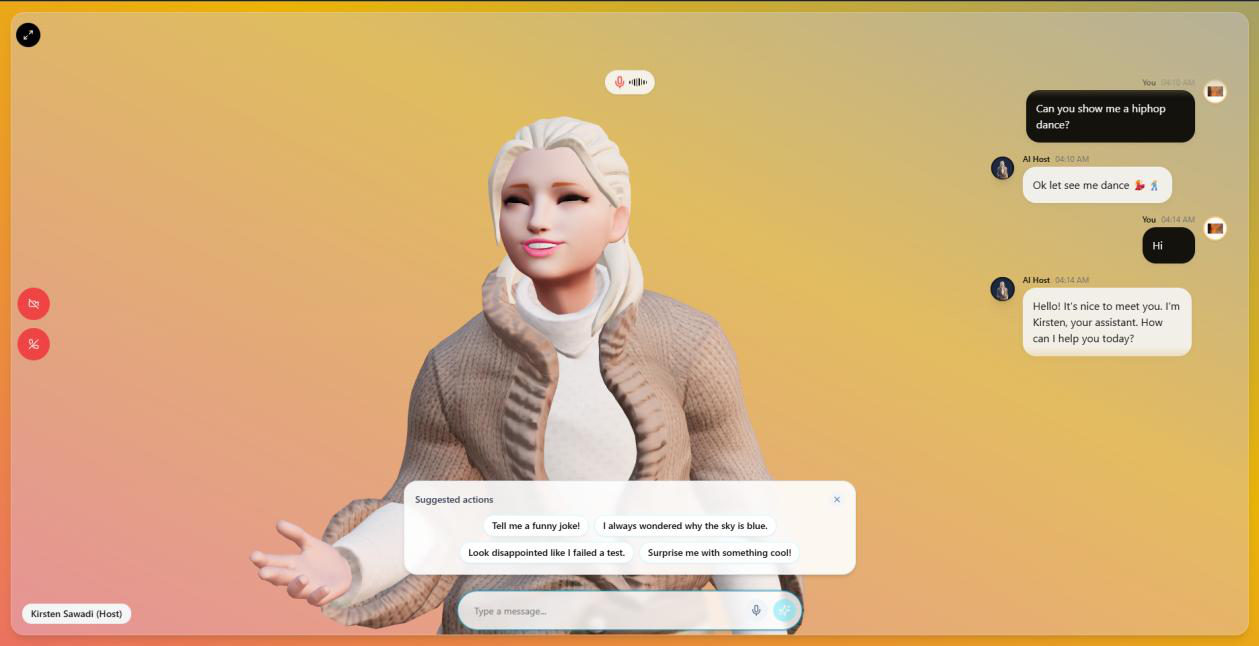
- thesis grade
- 94/100
- FPS in Chrome
- 60
- speech → reply
- ~9s
- ready personas
- 3
- Team
- Solo project
- Stack
- Next.jsTypeScriptReact Three FiberThree.jsZustandGroq (LLaMA 3.3 70B)ElevenLabsWeb Speech APIPrismaPostgreSQL
01 — The gap
Avatars could talk. None could hold a conversation.
Synthesia
pre-rendered video
NVIDIA Audio2Face
needs a dedicated GPU
Soul Machines
closed enterprise platform
Convai · MetaHuman
tied to Unreal Engine or VR
This project → live, unscripted voice conversation in any modern browser.
02 — How it works
One LLM call directs the whole performance.
- 1
Voice in
Web Speech API
- 2
LLM director
Groq · LLaMA 3.3 70B
- 3
Voice and visemes
ElevenLabs · Rhubarb
- 4
3D avatar
Three.js · 60 FPS
// real reply, per the contract in lib/prompt.ts
{
  "message": "Hmm, are you sure that's the best approach?",
  "voiceMessage": "Hmm, are you sure that's the best approach?",
  "voiceEmotion": "he said, confused",
  "facialExpression": "suprised",
  "animation": "Thinking",
  "question": { "choiceType": "default", "choices": ["Yes", "Not really"] }
}
03 — Built to feel human
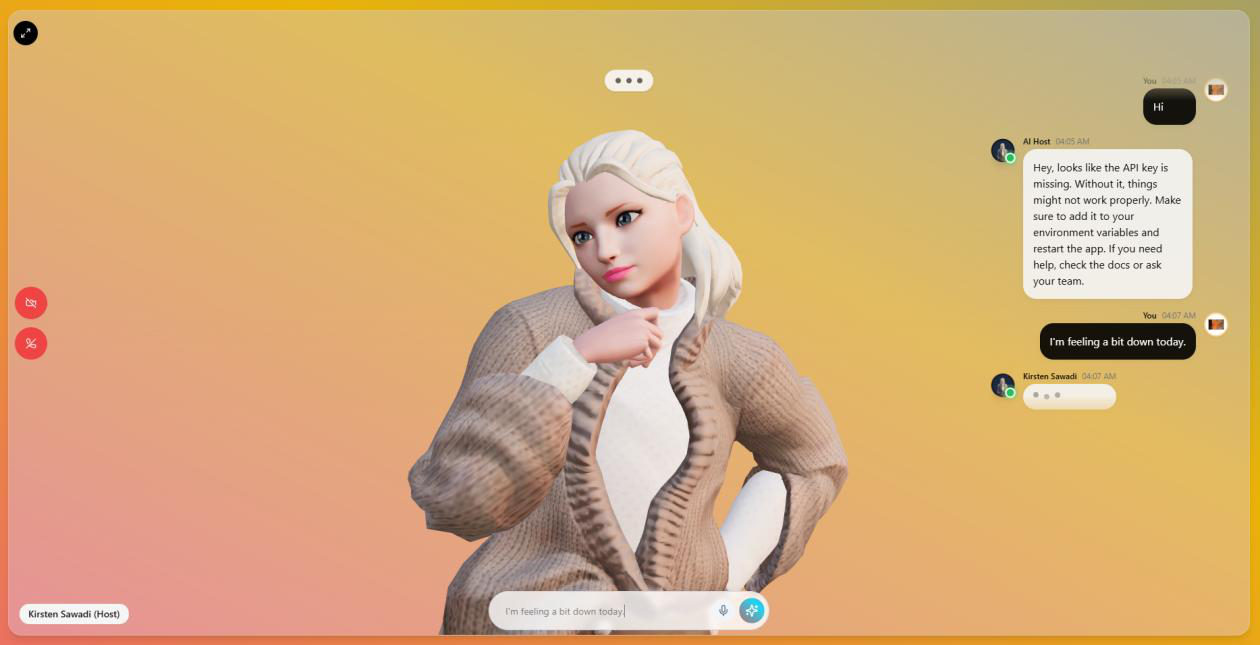
01
Thinks before it speaks
While the reply is being generated, the host strikes a thinking pose instead of freezing, so the pause reads as natural.
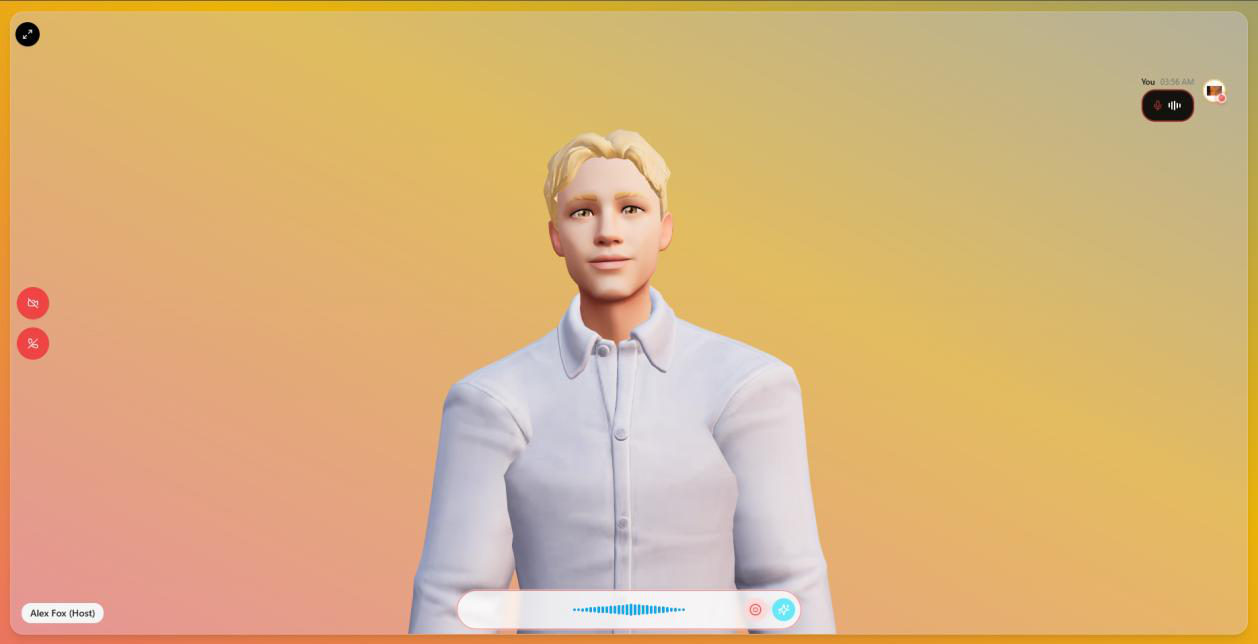
02
Listens when you cut in
Speak over the host and it stops mid-sentence: the stale request is aborted and the new message takes over, with no overlapping replies.
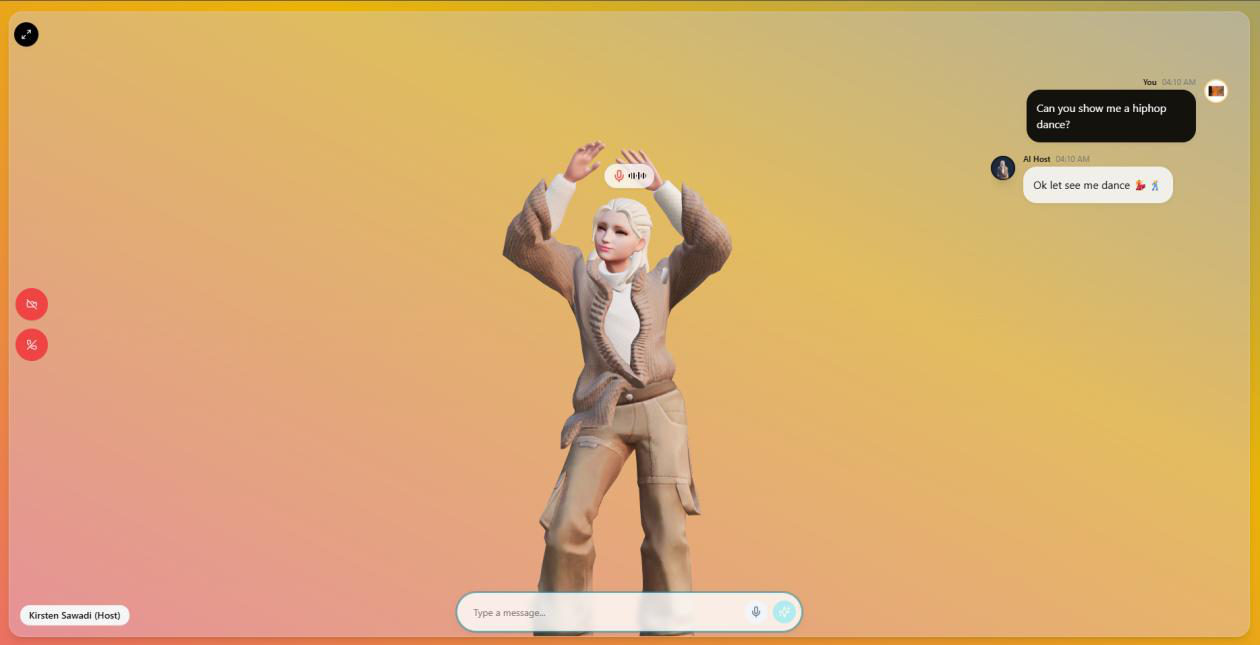
03
Voice, face and body agree
Each answer carries a voice emotion, facial expression and gesture chosen together, and lip-sync comes from a hand-built Rhubarb-to-Oculus viseme mapping.
04 — Results and limits
What worked
- Smooth 60 FPS rendering in Chrome
- About 96% of LLM replies match the JSON contract (estimated)
- Users bring their own API keys, so the platform has no per-conversation AI cost
What's next
- Cut ~9s latency by streaming the LLM reply and switching to Azure TTS
- Rhubarb covers 9 of 15 Oculus visemes; Azure TTS would give the full set
- Richer gesture library and dynamic expression blending
Screenshots
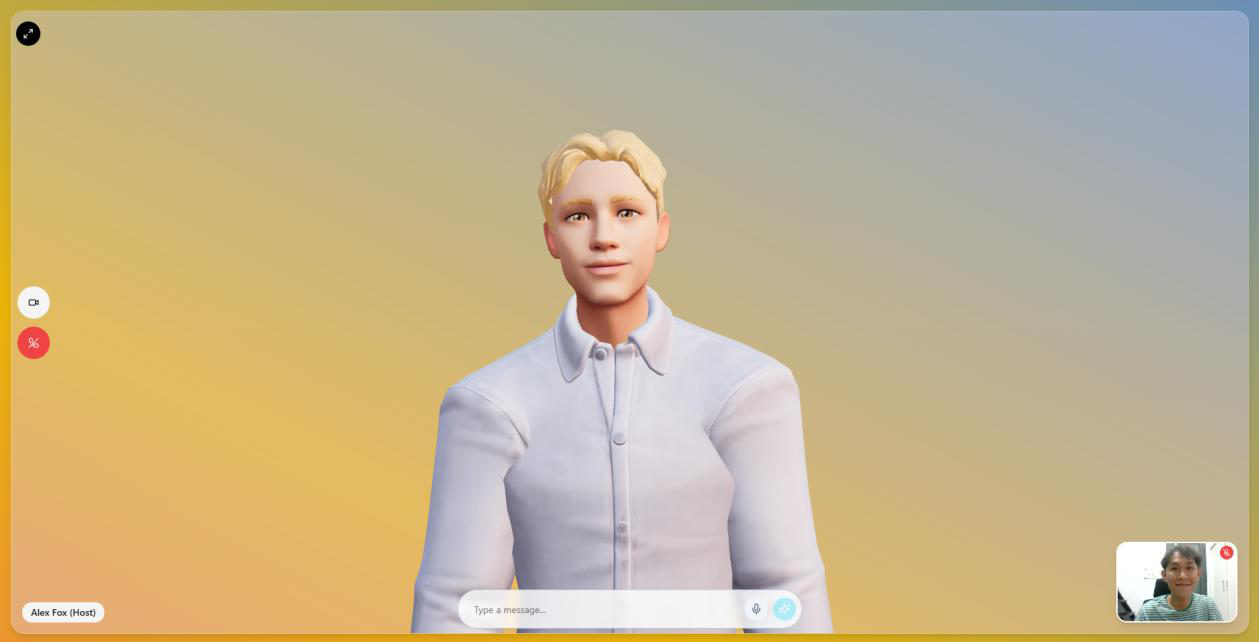
Meeting view with the 3D host
Voice input while the host listens
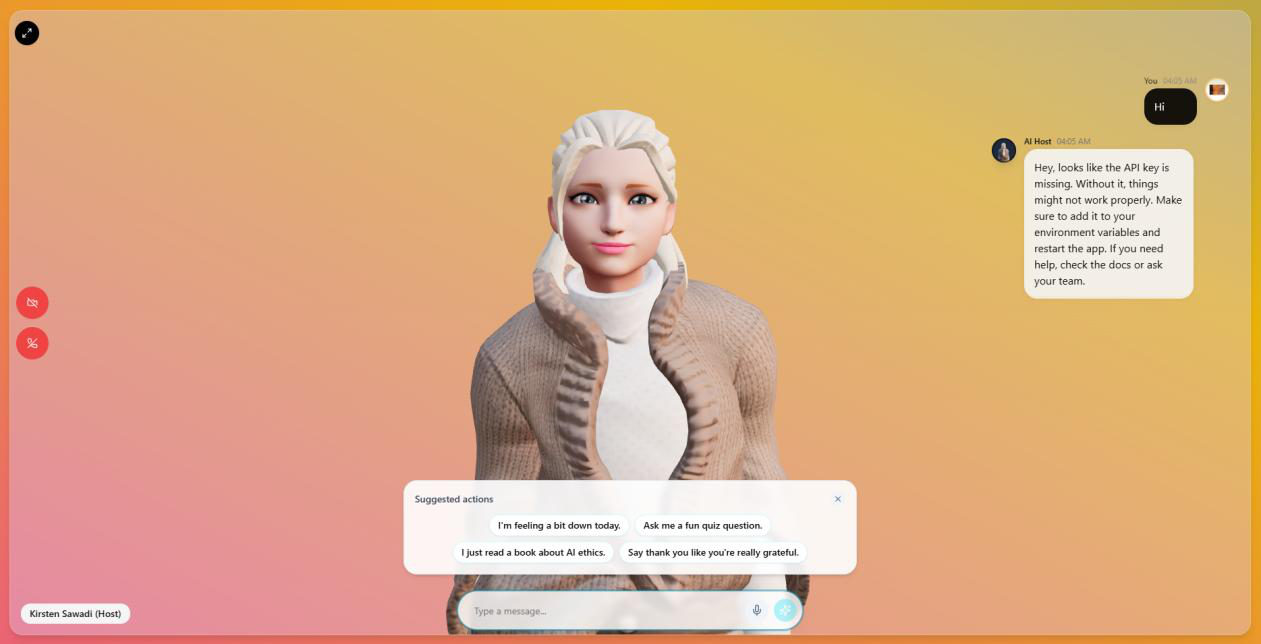
Suggested actions in text chat
Thinking pose while a reply is generated
Lip-sync and gesture while speaking
Full-body gesture on request
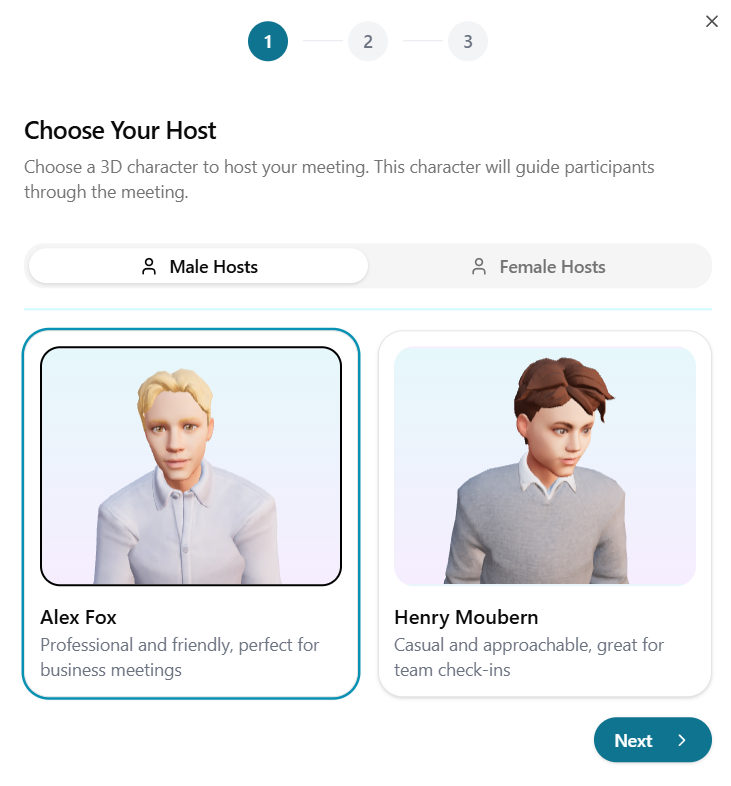
Choosing a host when creating a session